Documentation / 1.12.0
Why do answers in a long chat start slowly?
See how much of a chat each model skips reading again, and what to do when one reads it all every turn.
Before a model answers, it reads the whole chat so far. On a chat's later turns, it can skip the part it already read, kept in its prompt cache, and read only your new message. A model that can't skip reads a long chat from the start every turn, so its answers start later as the chat grows.
What you need
- A few chats of more than one turn from the last week, with models running on this computer.
Where to look
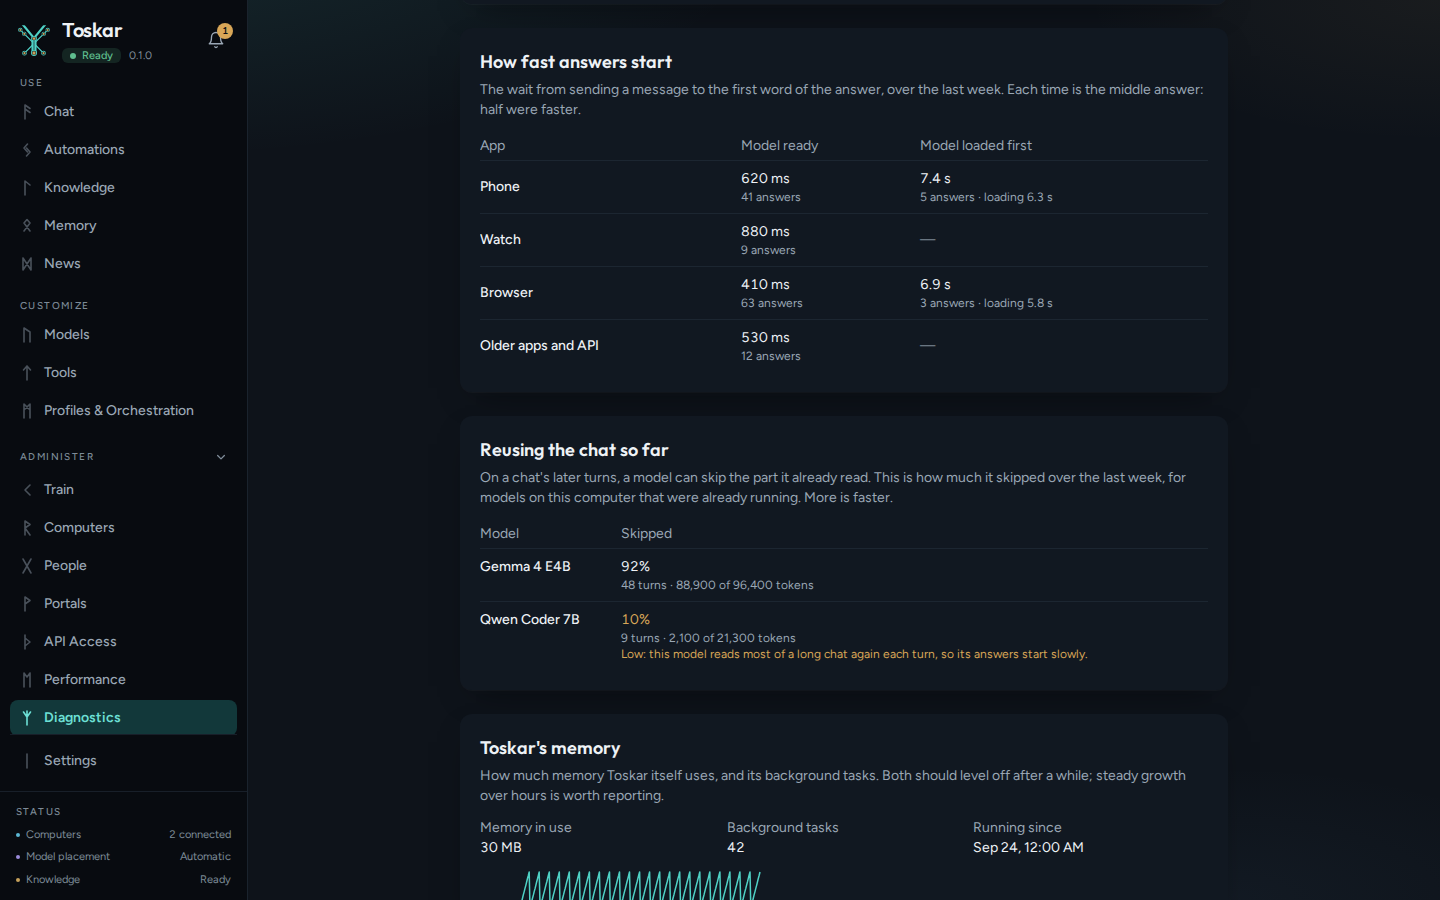
Open Diagnostics. Reusing the chat so far lists each model with the share of its later turns' prompts it skipped, and how many turns and tokens that covers.
| What it shows | What it means |
|---|---|
| 80% or more | Normal. Each turn reads little more than your new message. |
| Low, under 50% | Over at least five turns, the model read most of each chat again. Its answers slow down as a chat grows. |
| No panel | No chat had a second turn this week, or your models ran on another computer or app, which don't report this. |
Only turns after a chat's first are counted, and only when the model was already running. A model that just started has nothing to skip. Models on paired computers and in other apps, such as Ollama, don't report it, so they aren't listed.
Tip: Toskar's weekly tests hold a small model to 80% or more, and check that an answer from the cache matches one read from scratch, word for word.
Troubleshooting
When a model is marked low:
- Switch between chats less while you wait for answers. Each chat you send to the same model can push the others out of its cache.
- Try a different model for long chats. Some models, such as those with sliding-window attention, can't skip as much.
- Let a long chat be shortened. Auto-compact summarizes older turns, so there's less to read again.
- If a model stays low, report it from Diagnostics, so Toskar can tune how it runs that model.
These pages describe Toskar 1.12.0. Download 1.12.0 and its release notes ↗ · Need help? Report a bug or request a feature ↗